XCENA Showcases CXL Memory Innovations for AI Inference at OCP Global Summit 2026
XCENA Showcases CXL Memory Innovations for AI Inference at OCP Global Summit 2026
– XCENA and SK hynix are jointly optimizing RDMA-based shared-memory performance; their collaboration demo was featured at the SK hynix booth
– MX1 demonstrations show a KV cache shared across inference servers and near-data acceleration of RAG vector search
– CPO Harry Kim presents on near-data processing and, with Samsung Electronics, on CXL memory architecture for agentic AI; also joins an open-middleware panel with Marvell, Samsung, SK hynix and Gottbrath Technologies
– Distinguished Engineer Grant Mackey joins Microsoft, Seagate and Meta for an OCP Composable Memory Systems (CMS) Sub-Project technical update on addressing the memory wall for AI and general compute platforms
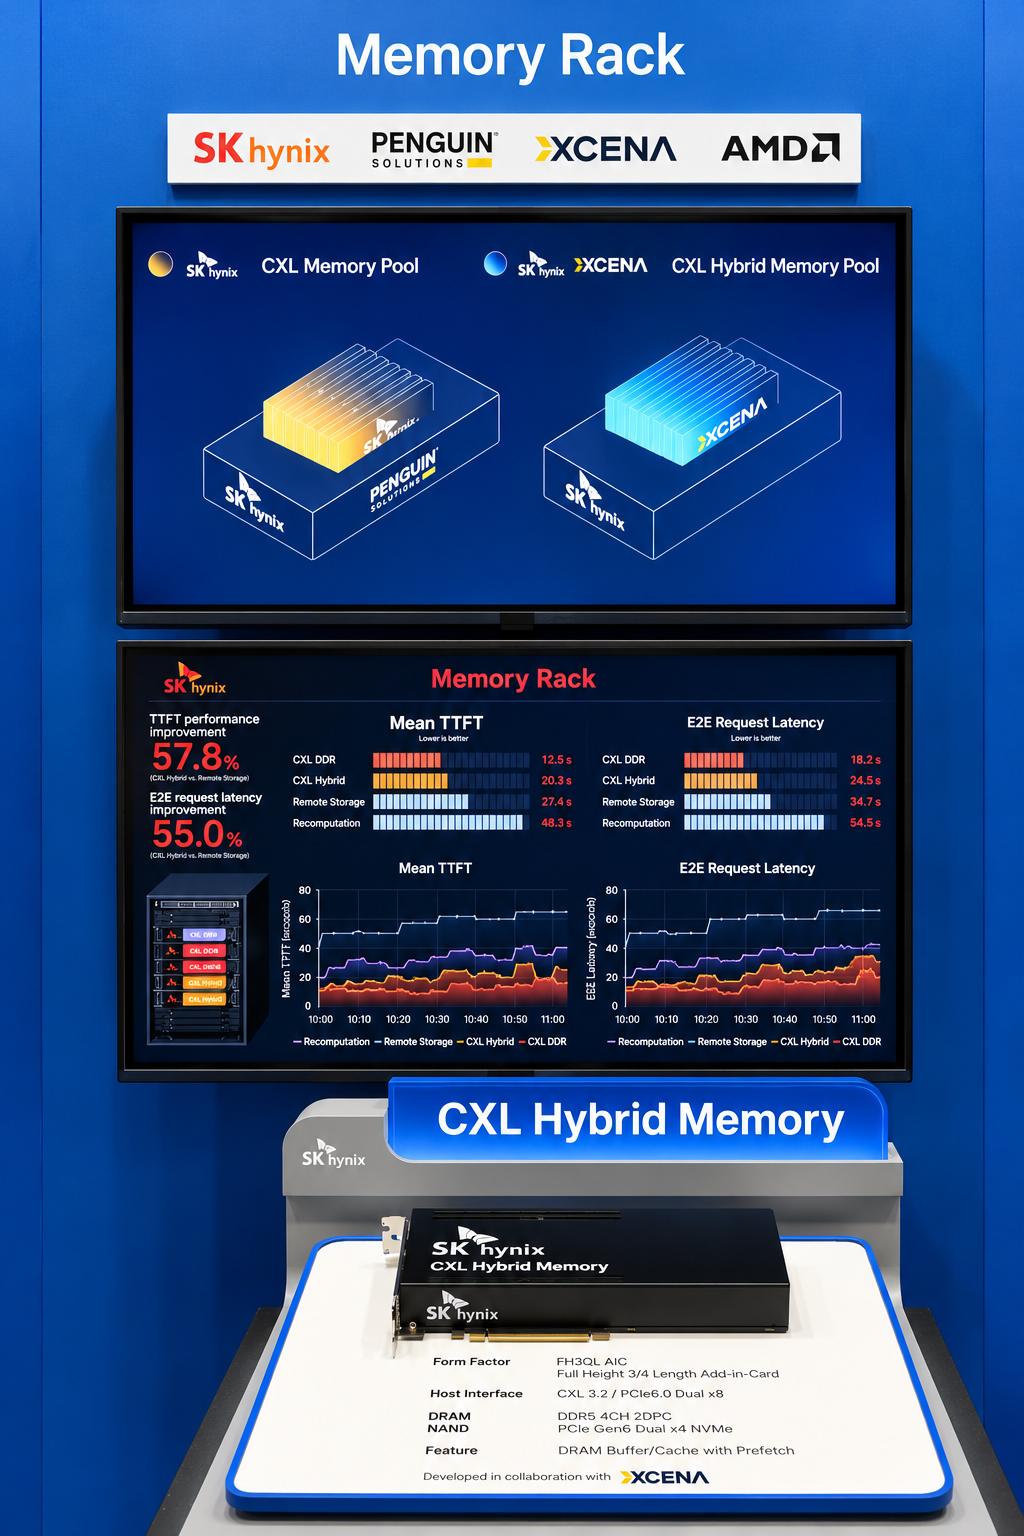
SK hynix’s CXL Hybrid Memory, built on XCENA's MX1 chip, on display at the SK hynix booth during OCP Global Summit 2026, held Oct. 12–15 (local time) at the San Jose Convention Center in California, USA. The two companies are jointly optimizing RDMA-based shared memory technology to improve AI inference performance.
SAN JOSE, Calif.--(BUSINESS WIRE)--XCENA, a fabless semiconductor company developing next-generation memory infrastructure for the AI era, demonstrated its CXL-based memory solutions for AI inference demonstrations at OCP Global Summit 2026, addressing AI inference’s growing memory requirements and data-movement burden. The event was held Oct. 12–15 at the San Jose McEnery Convention Center. The demonstrations address two of the biggest constraints on AI inference: growing memory requirements and the cost of moving data.
XCENA showed two AI inference use cases built on MX1, its Compute Express Link (CXL)-based computational memory solution.
The first demonstration showed multiple AI inference servers sharing a KV cache through a CXL memory pool. A KV cache stores context a model has already processed so it can be reused when generating responses. Keeping it in a shared pool, rather than duplicating it on every server, reduces redundant copies and data movement across servers.
The second used MX1’s near-data processing (NDP) capability to accelerate vector search, a core step in retrieval-augmented generation (RAG). MX1 runs the search in memory, where the data resides, rather than repeatedly moving large datasets to the host processor.
XCENA is also collaborating with SK hynix to apply a CXL hybrid memory architecture to AI workloads. Using InfiniteMemory®, MX1’s SSD-backed memory expansion capability, the two companies confirmed that the architecture can deliver significantly greater memory capacity scalability than conventional CMM-D while delivering higher performance than SSDs, and are now validating its applicability in real-world AI serving environments. At the summit, SK hynix unveiled “CXL Hybrid Memory” built on the MX1 chip and showcased an RDMA-based architecture using it.
Harry Kim, XCENA’s Chief Product Officer, presented a “Bringing General-Purpose Parallel Programming to Near-Data Processing” session on Oct. 14. He also joined Marvell, Samsung, SK hynix and Gottbrath Technologies for the panel “Beyond the Monolith: Open Middleware for Heterogeneous AI Infrastructure at Hyperscale.” Today, Kim co-presented “Disaggregated CXL Memory Architecture for Agentic AI: Dynamic Pooling, Sharing, and PNM Offloading” with Samsung Electronics.
Also today, Grant Mackey, Distinguished Engineer at XCENA, joined speakers from Microsoft, Seagate and Meta for the OCP Composable Memory Systems (CMS) Sub-Project technical update, “Addressing Memory Wall challenge for AI and General Compute platforms (CMS Sub-Project Technical Update).” The session covered CMS development progress and next steps for addressing the growing memory-capacity and bandwidth demands of AI and general-purpose computing.
“Improving AI infrastructure performance and efficiency is no longer solely a compute challenge. It also depends on how effectively memory is used and how much data movement can be eliminated,” said Jin Kim, CEO of XCENA. “At OCP, we demonstrated how MX1 supports real-world AI workloads, and we will keep working with partners across the ecosystem to advance next-generation AI memory infrastructure.”
About XCENA
XCENA is a memory-centric AI computing company redefining the role of memory in AI infrastructure. Built on the open Compute Express Link (CXL) standard, XCENA develops computational memory products that process data where it resides and enable memory to be expanded and utilized more efficiently, helping customers improve AI infrastructure performance while reducing latency, power consumption, and total cost of ownership (TCO).
Founded by semiconductor veterans from Samsung Electronics and SK hynix, XCENA combines expertise in semiconductor design with a full-stack software development kit (SDK) to help hyperscalers, cloud providers, and enterprises deploy and optimize AI infrastructure at scale. Headquartered in Seongnam, South Korea, with a U.S. office in Sunnyvale, California, XCENA has raised US$185 million to date, including a US$135 million Series B financing. Learn more at www.xcena.com.
Contacts
Media Contact
Steve Park, Head of Global Communications, XCENA
steve.park@xcena.com · media@xcena.com